Publications
Highlighted: first, co-first, or co-corresponding author · * equal contribution · † co-corresponding
2026
-
Structured State-Space Regularization for Generation-Friendly Image TokenizationIn NeurIPS, Dec 2026
-
-
EventCoT: Event-centric Video Chain-of-thought for Reasoning Temporal LocalizationIn arXiv preprint, Jul 2026
-
ACID: Action Consistency via Inverse Dynamics for Planning with World ModelsIn arXiv preprint, Jul 2026Planning with world models usually scores action sequences only by how close the predicted final state is to the goal, ignoring whether the intermediate transitions are physically realizable. ACID adds a cycle action-consistency term: an inverse dynamics model re-infers each action from the predicted transition, and the mismatch is added to the planning cost. Across four world models and six tasks, it improves planning and matches baseline accuracy with far less planning compute.
-
Planning in 8 Tokens: A Compact Discrete Tokenizer for Latent World ModelIn CVPR, Jun 2026(An early version appeared in LSRW workshop in CoRL 2025)Latent world models usually encode each observation with hundreds of tokens, which makes planning slow. CompACT is a discrete tokenizer that compresses an observation into as few as 8 tokens. An action-conditioned world model built on it plans competitively while running orders of magnitude faster.
2025
-
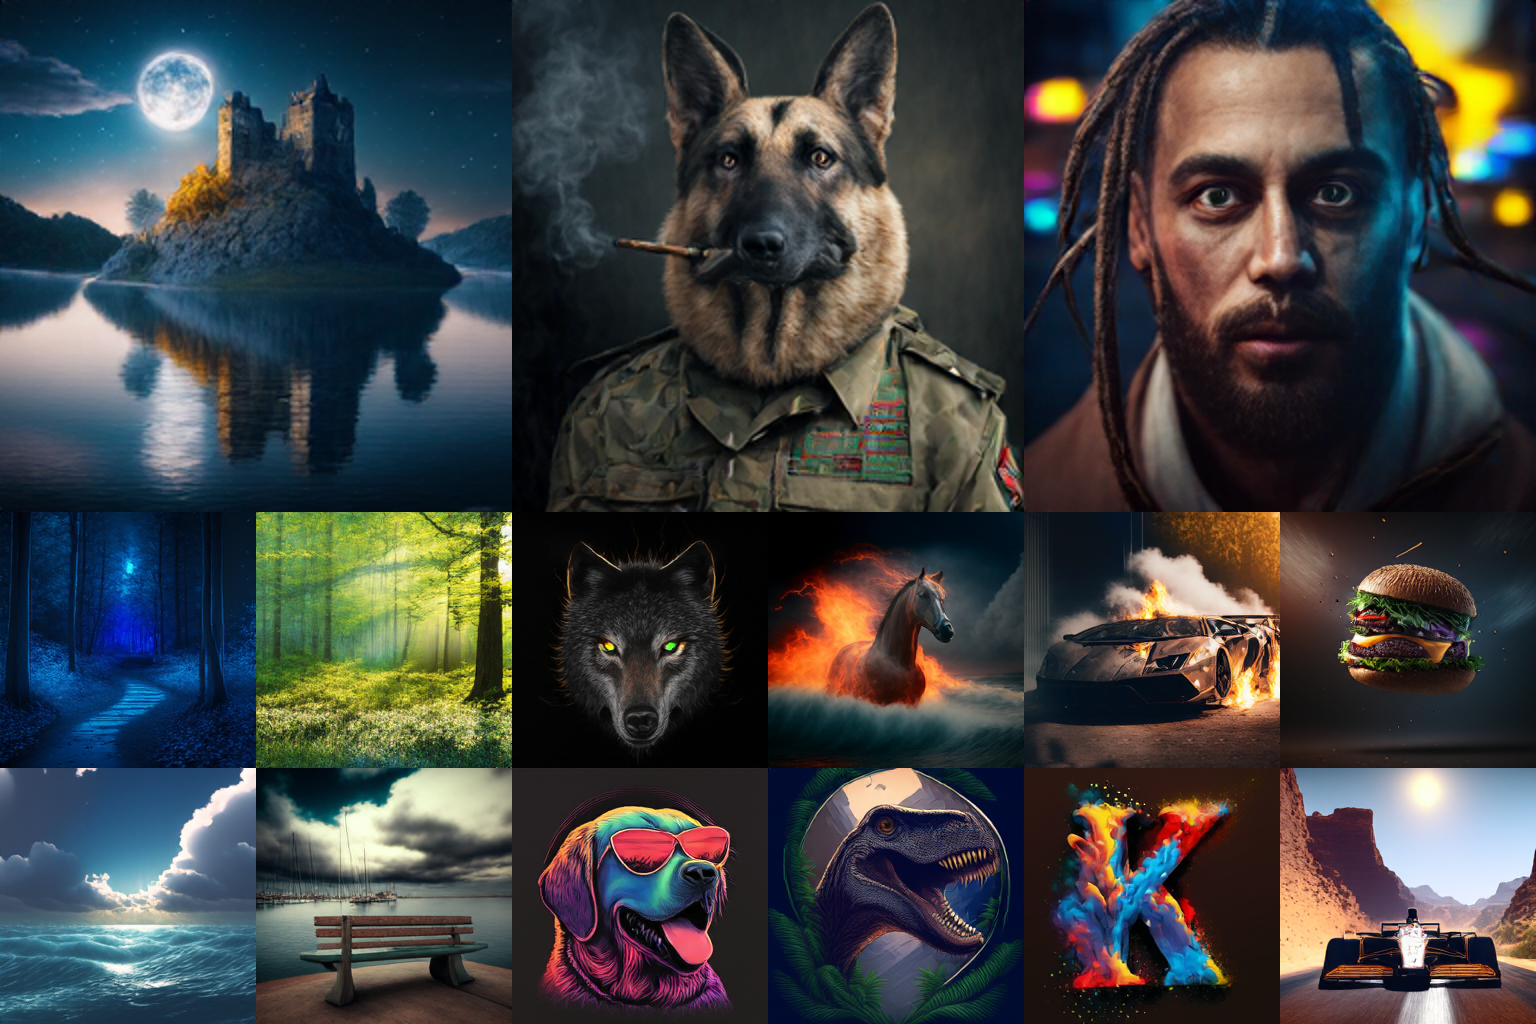 Democratizing Text-to-Image Masked Generative Models with Compact Text-Aware One-Dimensional TokensIn ICCV, Oct 2025TA-TiTok is a 1D image tokenizer, discrete or continuous, that uses text during de-tokenization and trains in a single stage, so it scales easily to large datasets. Building on it, MaskGen is a family of text-to-image masked generative models trained only on open data that performs comparably to models trained on private data.

2024
-
-
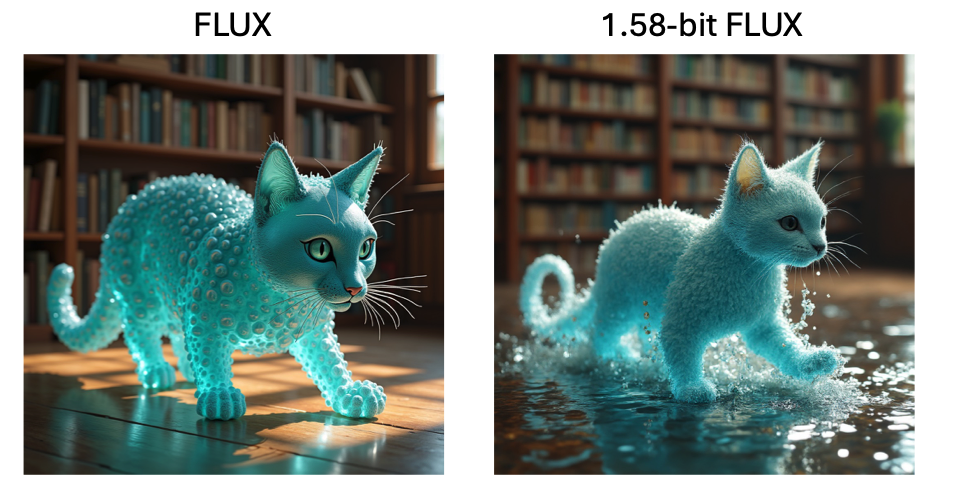
Bootstrapping Top-down Information for Self-modulating Slot AttentionIn NeurIPS, Dec 2024Bottom-up object-centric learning struggles when an object’s features vary widely in complex scenes. We add a top-down pathway to slot attention: the model first estimates object semantics from its own outputs, then uses them to steer attention toward relevant features. This gives state-of-the-art object discovery on synthetic and real-world benchmarks.
-
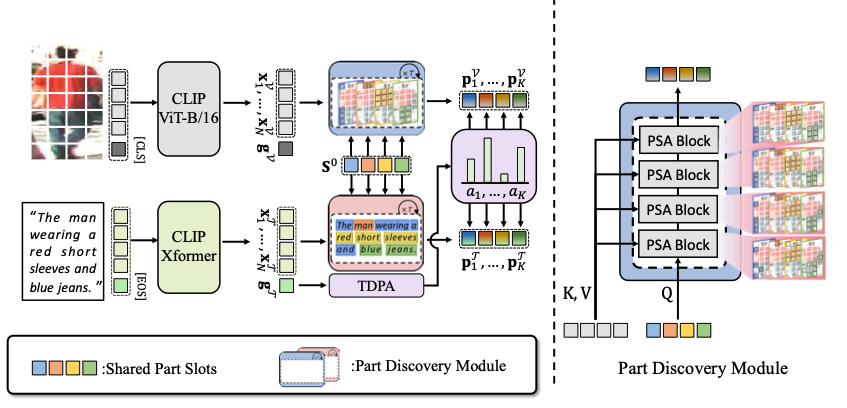 PLOT: Text-based Person Search with Part Slot Attention for Corresponding Part DiscoveryIn ECCV, Oct 2024
-


2023
-
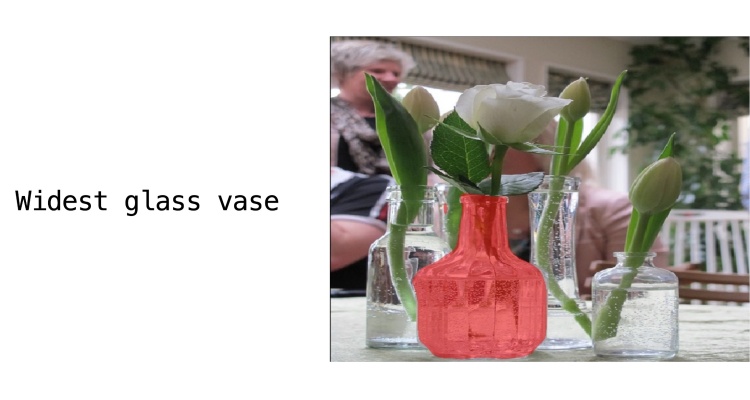
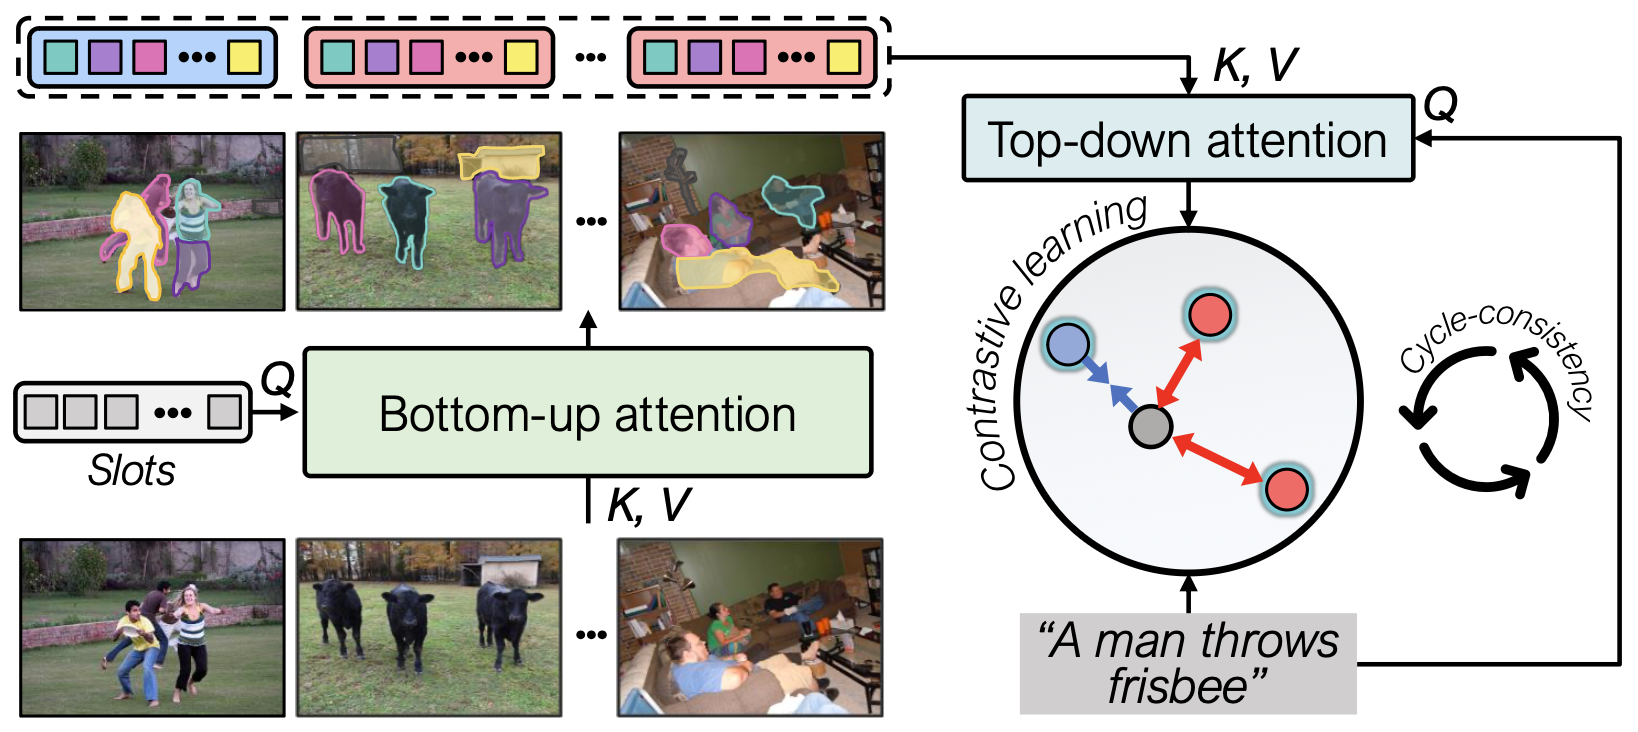 Shatter and Gather: Learning Referring Image Segmentation with Text SupervisionIn ICCV, Oct 2023We learn referring image segmentation using only text descriptions of the training images as supervision. The model first discovers semantic entities in an image, then gathers the ones relevant to the text query into the referent’s mask, trained with a loss that needs no extra labels. It outperforms prior weakly supervised and open-vocabulary segmentation methods on four benchmarks.
-
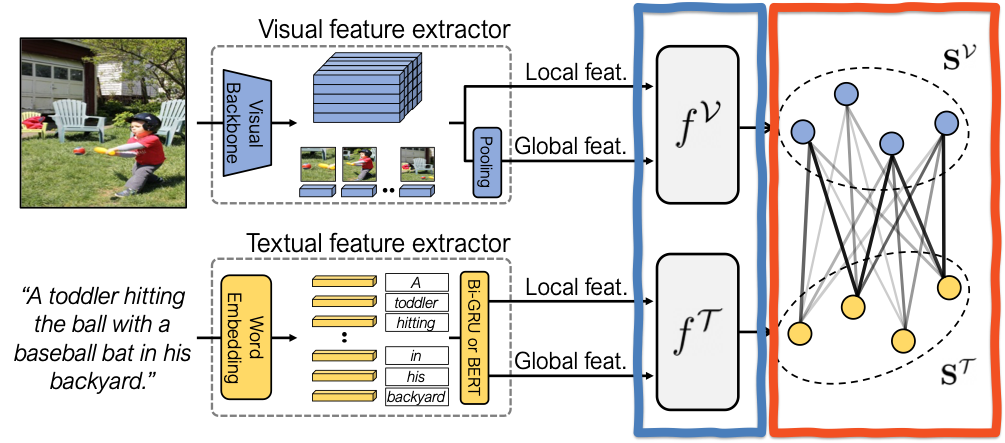 Improving Cross-Modal Retrieval With Set of Diverse EmbeddingsIn CVPR, Jun 2023In image-text retrieval, one image can match many captions and vice versa. We represent each sample as a set of diverse embeddings produced by a slot-attention-based set prediction module, and compare sets with a new smooth-Chamfer similarity. It outperforms prior methods on COCO and Flickr30K, including ones that need much more inference compute.(Highlight, 235/9155 = 2.5%)


